


The processor, also referred to as the central processing unit (CPU), is the most fundamental and the most important part of a computer. It is the part that executes all tasks (instructions) that are fed to the computer through program code. At the same time, peripheral devices, RAM and storage (hard drives, SSDs, oreven tape in the past) are connected to it in various ways. It is therefore truly the central element of a computer.
Today’s processors are extremely complex and sophisticated: the truly in-depth details of their architectures are entirely beyond the scope of this article, but we will try to give some insight into the features of modern advanced CPUs and how they work.
Elements of a core
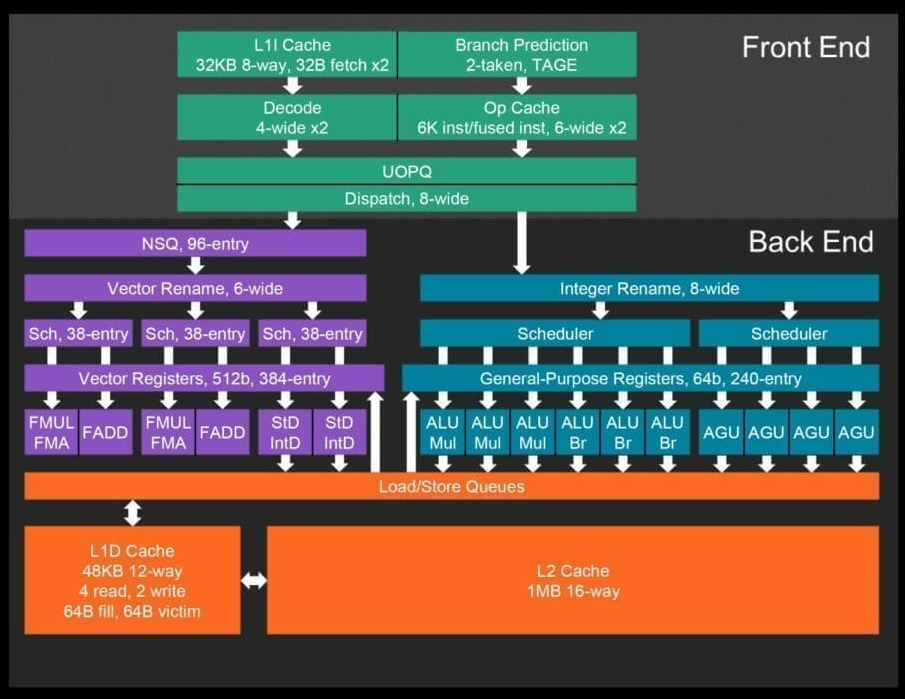
The structure of processor core architectures is very complex and also often varies. The main elements of a core are divided into the so-called frontend and backend. The frontend includes the first-level instruction cache (code), which is the primary place in the processor where program code is held during use. The processor fetches this code by instructions or by a block of a certain number of bytes, decodes individual instructions, which means it determines which instruction it is, and then issues it for further processing to the backend.
Modern processors often have an additional cache (MicroOP or µOP cache) that stores decoded instructions for later use without having to be decoded again.
The backend is the part of the processor that contains the units for executing instructions. These are mainly arithmetic logic units (ALU), which execute most of the general purpose instructions of the instruction set. Alongside them, the core also contains so-called Load/Store units. These serve to read data from memory (load) or write data to memory (store), and may support both or either types of operations. In addition to these units, there may be others present: for example, separate units solely for processing branch and jump operations.
Load/Store units do not work directly with operating memory; they are first connected to the first-level data cache and then the second-level cache (and then the third), through which data eventually reaches RAM. The first and second-level caches for data are therefore closely associated with the Load/Store units. These are also sometimes referred to as AGU, which refers to the function of generating the target address (Address Generation Unit) for memory operations.
An important part of the core is the registers, which are closely connected to the ALU and Load/Store units. Registers are sections of special SRAM-type memory directly in the core, into which operands are loaded from memory for processing by instructions, and from which data can then be loaded back into memory.
FPU (x87) and SIMD instructions have their own sets of registers and their own execution units, to which the SIMD and x87 registers are connected. These are essentially also ALUs, but ones capable of working with floating-point operands as well as with the contents of SIMD registers, consisting of a larger number of values at once—see the previous chapter.
Optimizing program execution
The original historical concept of a processor is that it processes instructions in the order in which they come in the program sequence, one after another, having to wait for the previous instruction to complete and write its results before starting the next. This is so-called “in-order” execution. However, respecting this natural structure of the program would significantly limit performance and processing speed. For example, because some operations (like division) take processors many cycles to finish. But mainly because when processing programs, idle periods arise quite frequently. The most common source of these is that the processor does not have the data from operating memory available that the next instruction needs to work with, and is waiting for it to arrive from memory into the cache and then into the working registers.
To improve performance (to increase the number of instructions processed per unit of time, for example per cycle or per 1 MHz of frequency—often referred to as “IPC,” which originally stands for instructions per cycle), it is necessary to execute instructions faster and more sophisticatedly.
Pipelining
A technique used practically universally today is to divide instruction processing into several different steps (stages) that form a pipeline, with each stage performing as much work as can be done in one cycle of the clock signal. Instructions of a program pass through this pipeline sequentially so that when one completes one stage (N), it moves to the next (N+1), and the next instruction enters the execution stage N.
With this processing method, the processor processes several instructions at once, their processing overlapping and each subsequent one being one cycle behind. Pipelining allowed a significant increase in CPU frequencies because the amount of work that the circuits had to perform in one clock cycle was reduced.
To illustrate, common pipeline stages in the first RISC processors using this principle were these, forming the so-called classic five-stage RISC pipeline:
- Fetching the instruction from the first-level instruction cache as a sequence of bits in which it is written in the program
- Decoding the instruction, where the processor determines from the instruction bits which operation it is and which registers to use, which are then read for the next stage
- Execution of the instruction, i.e., the actual arithmetic-logic operation performed in the ALU
- Memory access, if needed
- Writing the results back to registers
Modern processors, however, tend to have longer pipelines with a larger number of stages, into which these phases are further subdivided. A larger number of stages, each doing less work, allows the processor core to achieve a higher frequency.
Branch prediction and prefetch
The fact that instructions begin to execute not when the previous instructions are complete, but immediately after the previous ones have only started executing, has both performance benefits and its drawbacks. A consequence is, for example, that if a program encounters a branch instruction, it may not yet be clear which direction the execution flow will take, because, for example, an IF operation depends on a value that is yet to be provided by an instruction still being processed.
To avoid the processor having to wait, so-called branch predictors were developed. These attempt to predict which direction a branch or similar operation in the code will take, based on, for example, the program’s previous behavior (which works well for code loops), but also on recognizing other, more complex patterns. When the processor encounters a branch instruction, the branch predictor provides a prediction (speculation) of which direction the program will likely take (for example, whether it will jump to another address or continue without a jump), allowing processing to continue immediately.
The disadvantage is that if it turns out the branch prediction was incorrect once previous instructions finally complete, the processor must discard all subsequent instructions and results produced after the speculation and roll back. This requires complex logic and rigorous validation of correct operation. Every incorrectly speculated branch degrades performance, and the penalty is greater the more pipeline stages the processor has—more instructions typically have to be discarded. Improving branch predictors is therefore one of the most important parts of processor improvements, and each new generation of CPU cores strives to improve predictor capabilities by lowering the misprediction rate.
A similar problem and performance limitation as that involving branch predictors is addressed by the prefetch technique. Here, the problem is waiting for data from operating memory, which is relatively slow compared to the CPU and can take tens to hundreds of cycles to deliver data requested by the program being processed in the CPU. To operate at high performance, the processor must therefore request data from memory many cycles before it needs it.
Prefetching consists precisely of estimating in advance which data the processor will need and preloading it into the second and first-level caches, so that the processor finds it there (which is referred to as cache hit) and does not have to wait for delivery from RAM. Just as with branch predictors, the abilities of prefetch to identify patterns in memory access and preload data accordingly are constantly being improved. This technique is also critical for improving CPU performance.
Superscalar processors
After processors implemented pipelining, the next step in improving performance was parallel instruction processing. As mentioned, in a program’s code, instructions follow one another, but it is not true that they always depend on the previous one (in the sense that the result of the first is one of the inputs of the second, so it must wait for it). The inputs of the current instruction can be data that was prepared by instructions further in the past. Then it is possible to process this instruction simultaneously with the one preceding it.

Superscalar processors take advantage of this and have multiple parallel units in the core (ALUs, FPU pipelines, Load/Store units). The more parallel units of one type there are in the core, the more instructions that are not dependent on each other can be processed in one cycle, provided the opportunity arises.
In-Order and Out-of-Order execution
When combining pipelining and superscalar architecture, the presence of dependencies between instructions quickly becomes a limit on how often parallel units can be used simultaneously. The next step in improving performance (IPC) is the transition from strictly in-order execution to so-called out-of-order execution, which means instructions can be executed ahead of time and in a different order than what is their order in the code. This is a technique that significantly improves performance, but also increases the complexity of processors and the difficulty of verifying their correct behavior and eliminating logic errors.
In out-of-order program execution, the processor is not bound by the order of instructions, only by their actual dependencies. If the processor has free execution units for the current cycle, it can issue not only the next instruction in line for execution, but also other instructions that follow later in the program—provided they do not depend on the result of any yet-unfinished instruction. An out-of-order processor always analyzes a certain “window” of the program code from which it can “pick out” instructions ahead for immediate execution, allowing the remaining dependent instructions to be processed faster once their inputs are ready. The original order of program operations is then restored during the writing of results back (referred to as retire phase).
Using out-of-order execution again increases the number of instructions the processor can execute per cycle, and thus performance. Out-of-order execution allows more efficient use of the execution units available to the processor core, as they will less often stay idle waiting for an instruction to execute.
The success of this technique depends on the size of the program “window” that the CPU sees, within which it can find instructions that can be executed immediately. Out-of-order processors use a queue or buffer typically called a Re-Order Buffer (ROB). This has a certain number of entries within which out-of-order instruction execution can be performed. Initially, it might have been only tens of entries, but in current processors, the depth can be up to several hundred entries. This then provides significantly better opportunities to execute instructions optimally out of order and utilize as many parallel units simultaneously as possible. Some of today’s processors can thus have 8 or more parallel ALUs and additional Load/Store units.
Out-of-order processors also have other queues with a similar purpose. For example, Load/Store units use a queue for load operations (reading data from memory), within which operations can also be executed out of order, and similarly, there is a queue for store operations (writing data to memory).
Modern processors strive to continuously improve single-threaded performance (which is then multiplied into multi-threaded performance by multiple cores). The means to this end is the diligent pursuit of small cumulative improvements using all these techniques simultaneously: that is, increasing the number of parallel units in the processor, deepening the Re-Order Buffer and other queues used for out-of-order instruction execution, and improving prefetch and branch prediction. All of this can incrementally increase the core’s IPC (performance per 1 MHz). At the same time, processor architects must optimize the number of pipeline stages and the amount of work done by individual stages to allow the processor to achieve the best possible frequency.
Neither maximum frequency nor maximum IPC alone is sufficient for top-tier performance. Performance is given by the product of frequency and IPC, so for high performance, processors must utilize both of these sources in some combination. Many other techniques are also employed within the processor architecture that contribute either to increasing frequency or to improving IPC, and which cannot be easily listed or described in one place. Their combination makes the modern microprocessors some of the most complex mechanisms in the world. Their fast and, above all, correct and reliable operation without unforeseen deviations from expected behavior is, without exaggeration, a marvel of technology.
English translation and edit by Jozef Dudáš
⠀



If anything doesn’t seem factually correct to you, please let us know—either in the comments or by email at info@hwcooling.net. I’ll forward everything to the author. The goal is to make sure that everything in the article is correct.